Pre-Winter Sale Special Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: xmas50

Databricks Databricks-Certified-Data-Analyst-Associate - Databricks Certified Data Analyst Associate Exam

A data analyst has created a user-defined function using the following line of code:

CREATE FUNCTION price(spend DOUBLE, units DOUBLE)

RETURNS DOUBLE

RETURN spend / units;

Which of the following code blocks can be used to apply this function to the customer_spend and customer_units columns of the table customer_summary to create column customer_price?

A.

SELECT PRICE customer_spend, customer_units AS customer_price FROM customer_summary

B.

SELECT price FROM customer_summary

C.

SELECT function(price(customer_spend, customer_units)) AS customer_price FROM customer_summary

D.

SELECT double(price(customer_spend, customer_units)) AS customer_price FROM customer_summary

E.

SELECT price(customer_spend, customer_units) AS customer_price FROM customer_summary

A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.

As a result, they have the following code block:

num_evals = 100

trials = SparkTrials()

best_hyperparam = fmin(

fn=objective_function,

space=search_space,

algo=tpe.suggest,

max_evals=num_evals,

trials=trials

)

Which of the following changes do they need to make to the above code block in order to accomplish the task?

A.

Change SparkTrials() to Trials()

B.

Reduce num_evals to be less than 10

C.

Change fmin() to fmax()

D.

Remove the trials=trials argument

E.

Remove the algo=tpe.suggest argument

A data analyst is working with gold-layer tables to complete an ad-hoc project. A stakeholder has provided the analyst with an additional dataset that can be used to augment the gold-layer tables already in use.

Which of the following terms is used to describe this data augmentation?

A.

Data testing

B.

Ad-hoc improvements

C.

Last-mile

D.

Last-mile ETL

E.

Data enhancement

Consider the following two statements:

Statement 1:
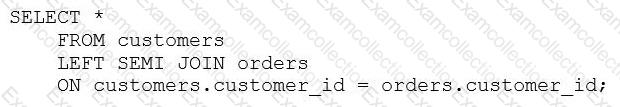
Statement 2:

Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?

A.

The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.

B.

When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.

C.

There is no difference between the result sets for both statements.

D.

Both statements will fail because Databricks SQL does not support those join types.

E.

When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.

A data engineer wants to schedule their Databricks SQL dashboard to refresh once per day, but they only want the associated SQL endpoint to be running when it is necessary.

Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?

A.

They can ensure the dashboard’s SQL endpoint matches each of the queries’ SQL endpoints.

B.

They can set up the dashboard’s SQL endpoint to be serverless.

C.

They can turn on the Auto Stop feature for the SQL endpoint.

D.

They can reduce the cluster size of the SQL endpoint.

E.

They can ensure the dashboard’s SQL endpoint is not one of the included query’s SQL endpoint.

Which of the following is a benefit of Databricks SQL using ANSI SQL as its standard SQL dialect?

A.

It has increased customization capabilities

B.

It is easy to migrate existing SQL queries to Databricks SQL

C.

It allows for the use of Photon ' s computation optimizations

D.

It is more performant than other SQL dialects

E.

It is more compatible with Spark ' s interpreters

Which of the following statements describes descriptive statistics?

A.

A branch of statistics that uses summary statistics to quantitatively describe and summarize data.

B.

A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.

C.

A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.

D.

A branch of statistics that uses summary statistics to categorically describe and summarize data.

E.

A branch of statistics that uses quantitative variables that must take on an uncountable set of values.

A data analyst has created a Query in Databricks SQL, and now they want to create two data visualizations from that Query and add both of those data visualizations to the same Databricks SQL Dashboard.

Which of the following steps will they need to take when creating and adding both data visualizations to the Databricks SQL Dashboard?

A.

They will need to alter the Query to return two separate sets of results.

B.

They will need to add two separate visualizations to the dashboard based on the same Query.

C.

They will need to create two separate dashboards.

D.

They will need to decide on a single data visualization to add to the dashboard.

E.

They will need to copy the Query and create one data visualization per query.

Data professionals with varying responsibilities use the Databricks Lakehouse Platform Which role in the Databricks Lakehouse Platform use Databricks SQL as their primary service?

A.

Data scientist

B.

Data engineer

C.

Platform architect

D.

Business analyst

A data analysis team has noticed that their Databricks SQL queries are running too slowly when connected to their always-on SQL endpoint. They claim that this issue is present when many members of the team are running small queries simultaneously. They ask the data engineering team for help. The data engineering team notices that each of the team’s queries uses the same SQL endpoint.

Which of the following approaches can the data engineering team use to improve the latency of the team’s queries?
A.

They can increase the cluster size of the SQL endpoint.

B.

They can increase the maximum bound of the SQL endpoint’s scaling range.

C.

They can turn on the Auto Stop feature for the SQL endpoint.

D.

They can turn on the Serverless feature for the SQL endpoint.

E.

They can turn on the Serverless feature for the SQL endpoint and change the Spot Instance Policy to “Reliability Optimized.”