Microsoft AI-300 - Operationalizing Machine Learning and Generative AI Solutions
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data.
The training_data argument specifies the path to the training data in a file named dataset1.csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python script.py dataset1.csv
Does the solution meet the goal?
Fabrikam Inc. must improve its deployment process because traditional machine learning models are deployed manually and the organization has limited rollback capability .
You need to recommend a deployment approach that supports staged rollout and rollback while minimizing operational overhead.
Which deployment approach should you recommend?
Fabrikam Inc. needs to improve the performance of a GPT-5 model based on the stated technical requirements.
Which action should you perform first?
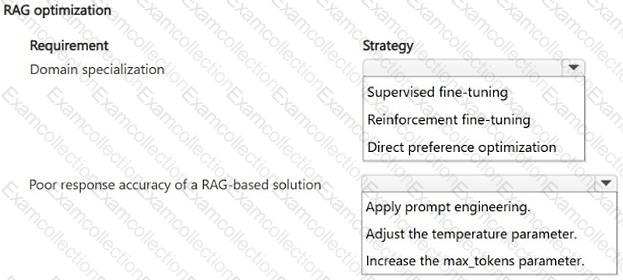
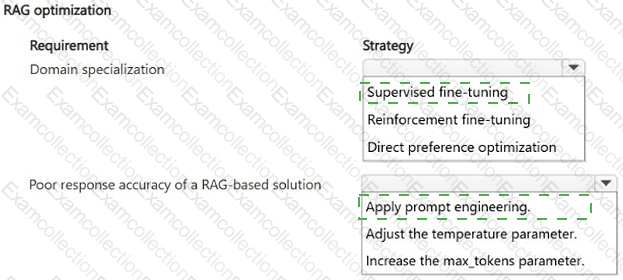
You need to configure an optimization method to meet Fabrikam Inc.’s technical requirements.
Which strategy should you apply first? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
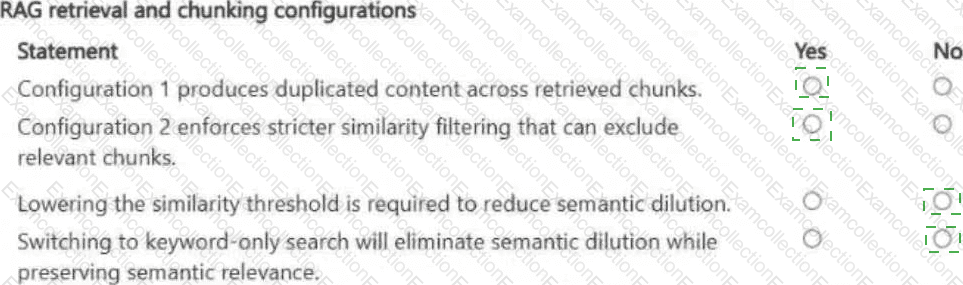
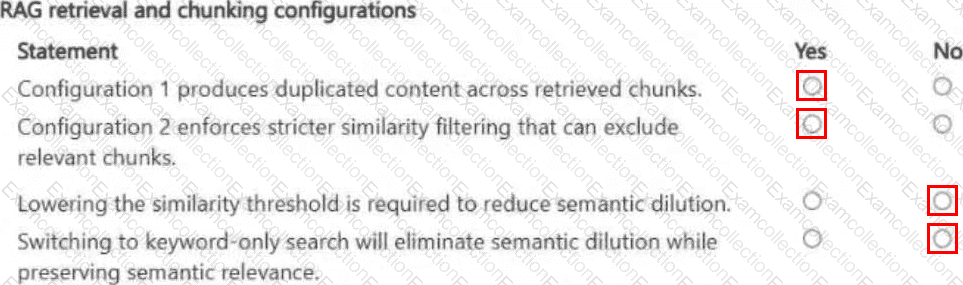
You manage a Retrieval-Augmented Generation (RAG) system that retrieves internal policy documents from a vector index.
Recent analysis shows that:
Retrieved results frequently include duplicated content from the same document.
Retrieved chunks sometimes span unrelated policy sections.
You review the following retrieval and ingestion configurations:
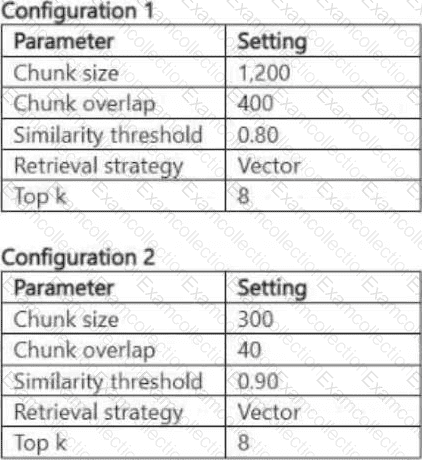
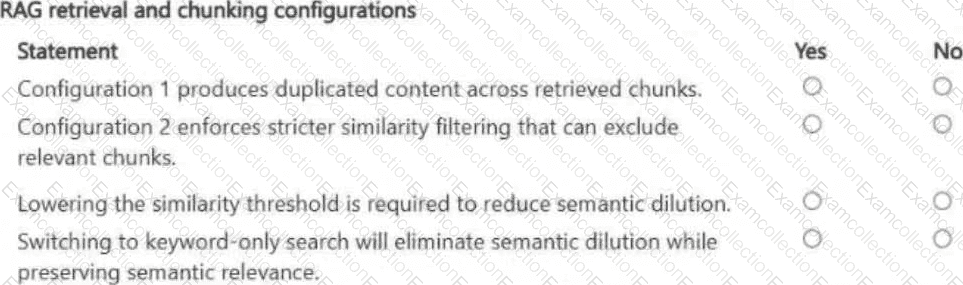
You need to reduce duplicated retrieval results and improve chunk relevance across policy sections.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.’s issues, constraints, and technical requirements.
What should you implement?
You need to recommend an experiment-tracking strategy that ensures consistent experiment results.
What should you recommend?
You have an Azure Machine Learning workspace.
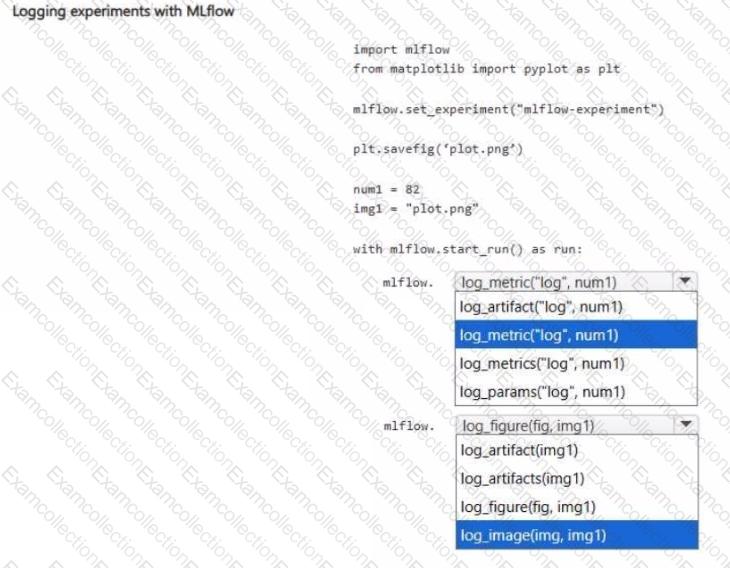
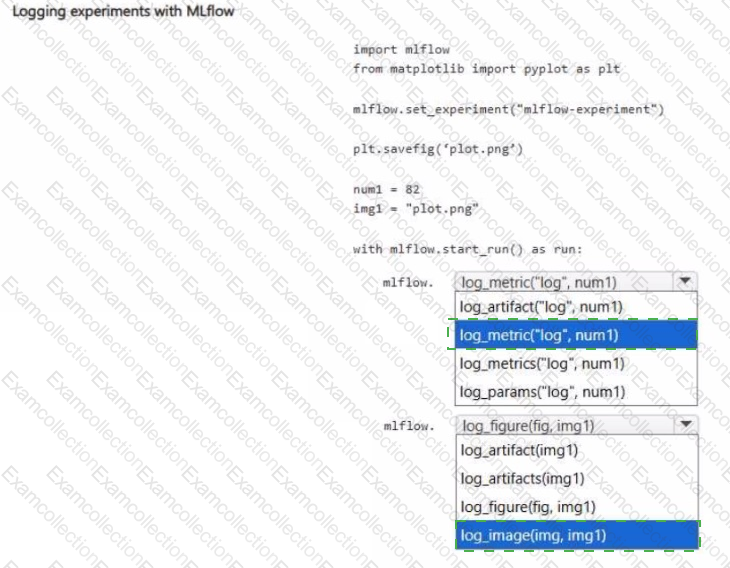
You plan to set up logging and tracking experiments by using MLflow Tracking.
You need to log the accuracy as a numerical value and the training loss as a plot.
How should you complete the commands? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
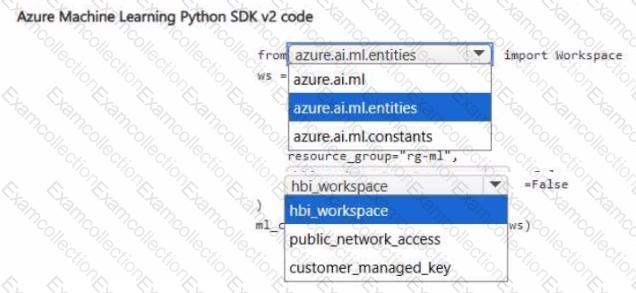
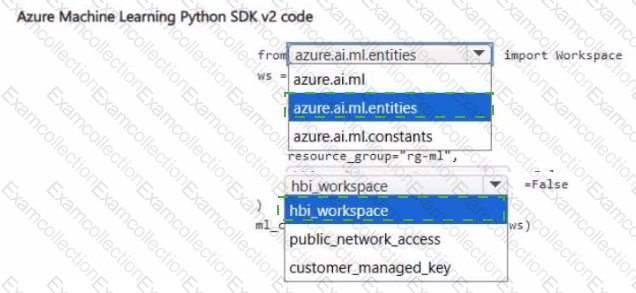
You have an Azure subscription that contains a resource group named rg-ml.
You plan to create an Azure Machine Learning workspace named workspacel in rg-ml by using Azure Machine Learning Python SDK v2.
You need to ensure workspacel is configured to prevent the collection of potentially sensitive data by Microsoft diagnostics.
How should you complete the provided code? To answer, select the appropnate options in the answer area.
NOTE: Each correct selection is worth one point.
You manage an Azure Machine learning workspace named workspace1.
You must develop Python SDK v2 code to add a compute instance to workspace1. The code must import all required modules and call the constructor of the Compute instance class.
You need to add the instantiated compute instance to workspace 1.
What should you use?